

I built an internal AI content platform that turns each new episode across roughly 100 podcast feeds into searchable, structured and publishable content. It replaced a manual growth ceiling with a continuous pipeline from audio to transcription, enrichment, indexing and distribution.
The problem
A large audio archive is valuable but nearly invisible to search engines and difficult for listeners to explore. Manual transcription and metadata work could never keep pace with the number of shows and new episodes.
The pipeline
- Detect and retrieve. MySQL tracks feeds and identifies new episodes for automated download.
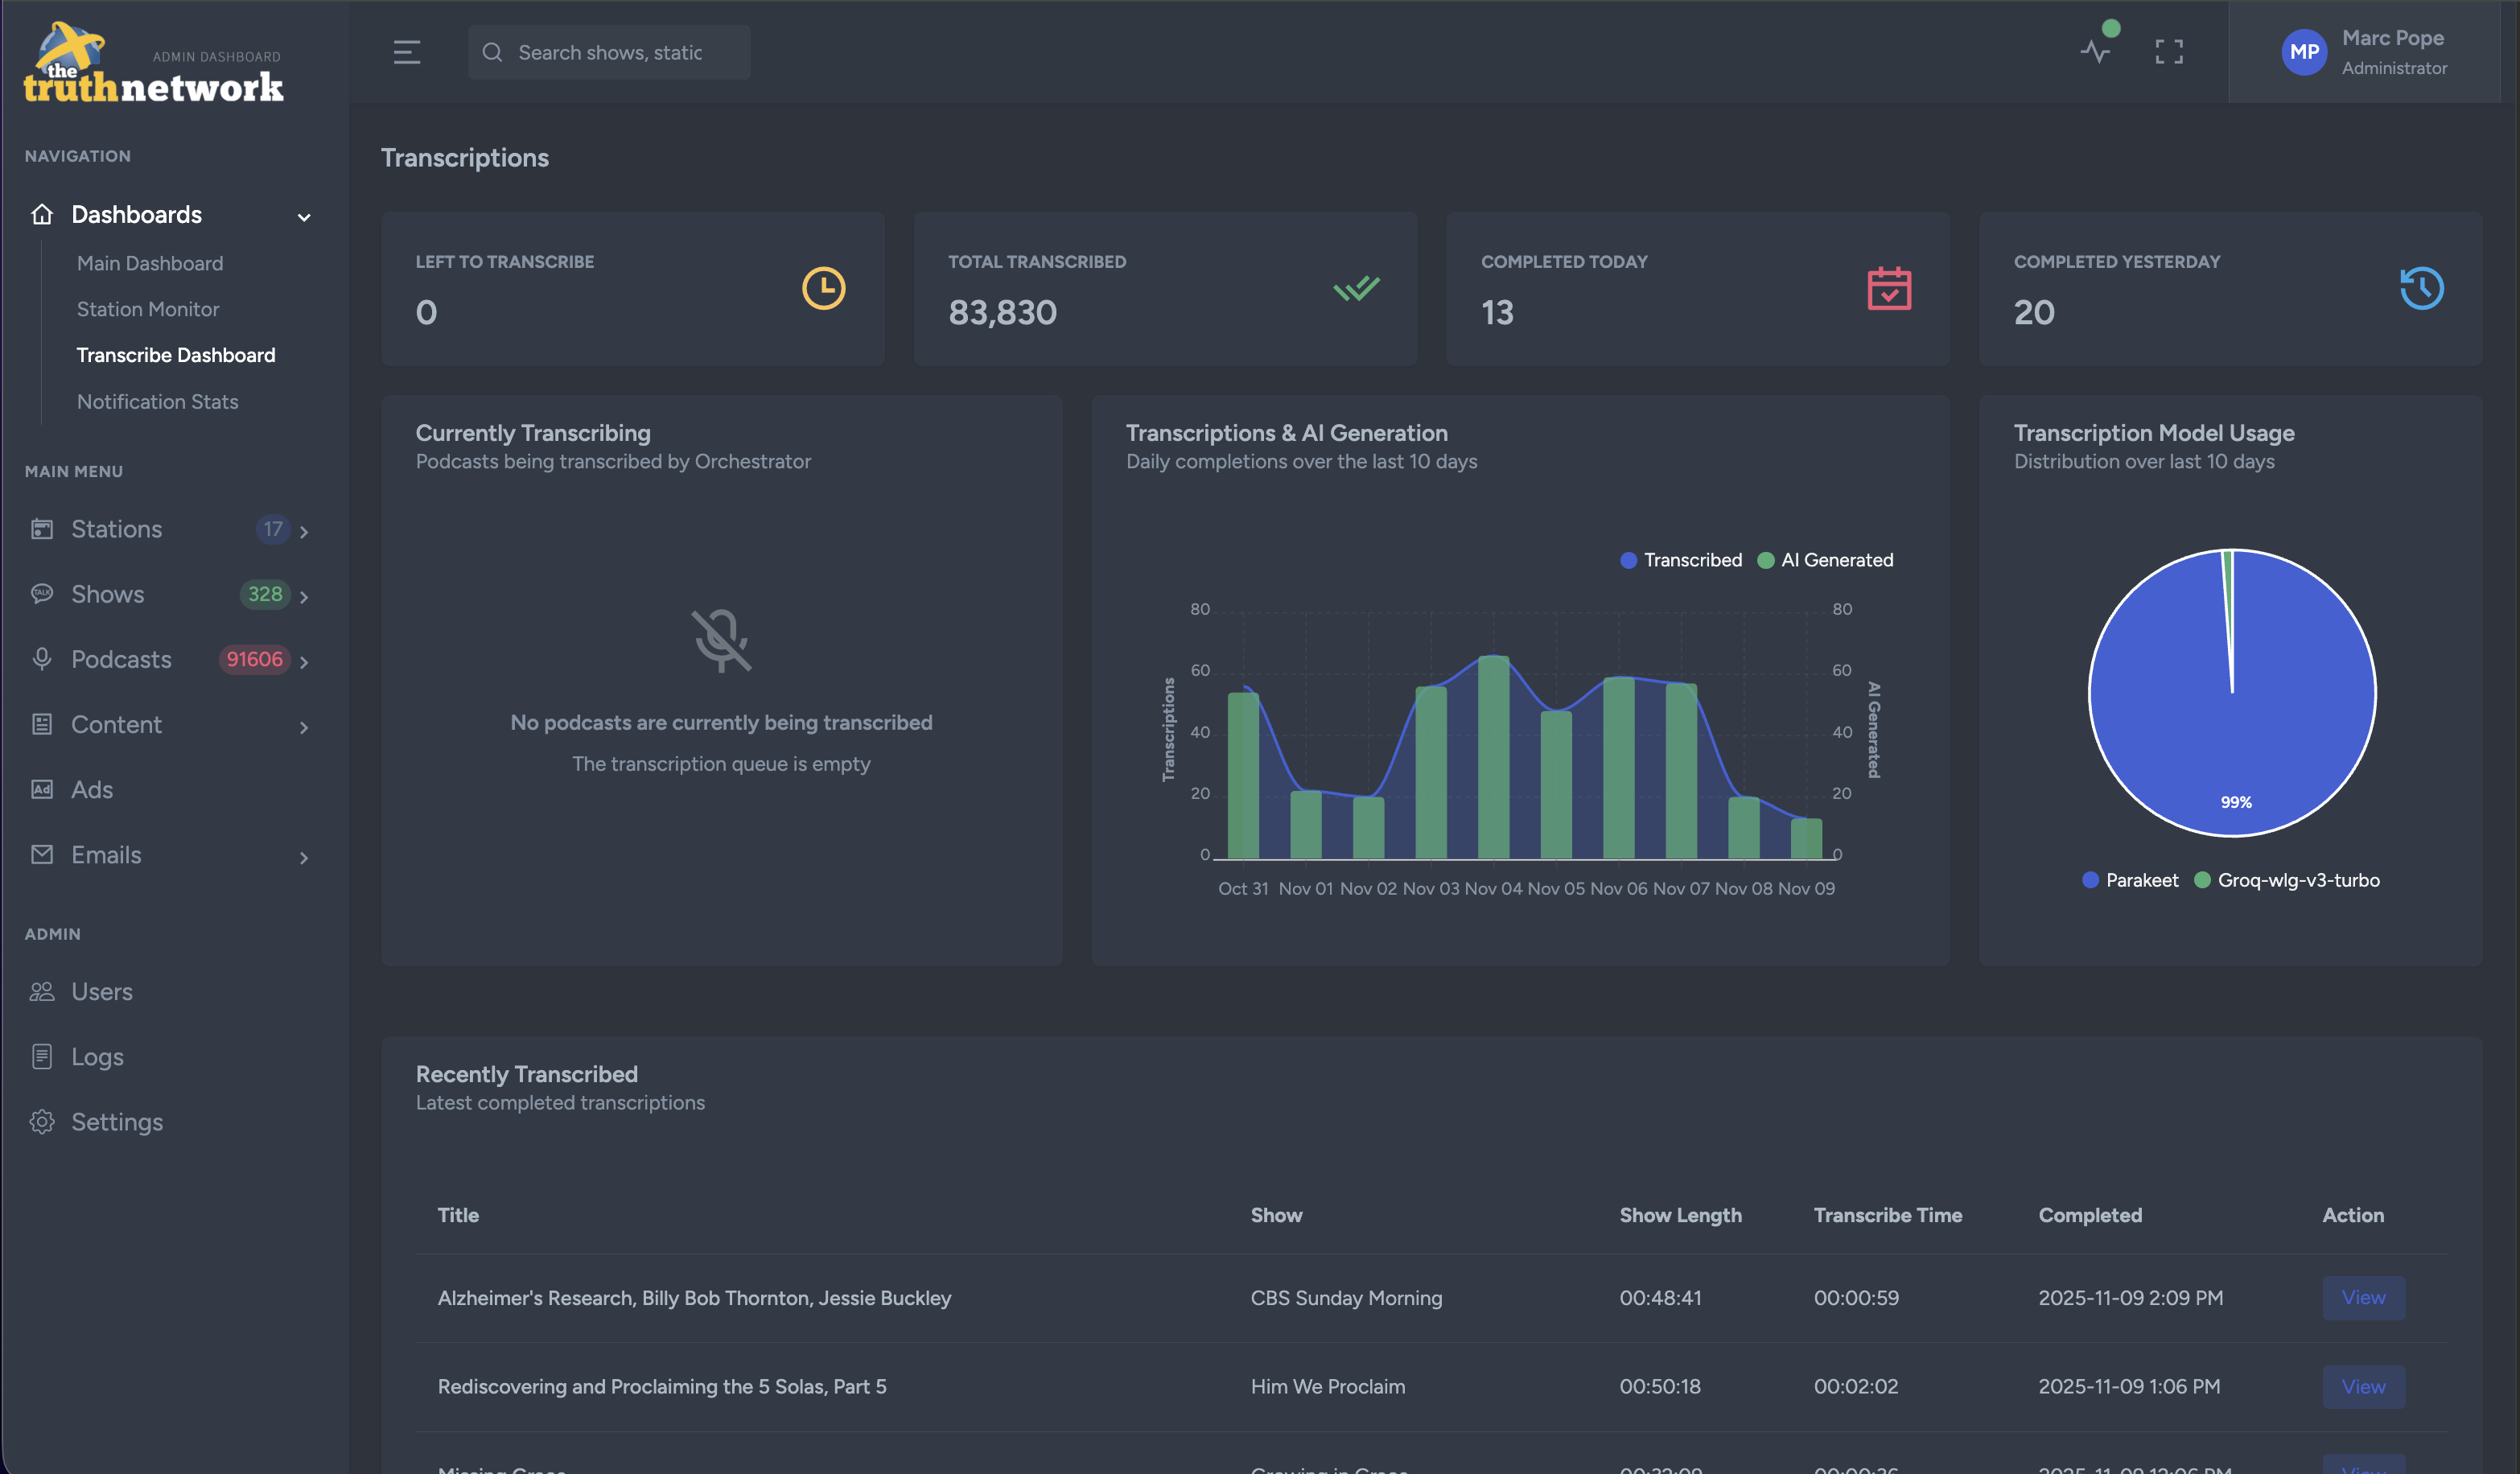
- Transcribe efficiently. A custom Docker image runs NVIDIA Parakeet on low-cost cloud GPUs, with Groq as a fallback.
- Enrich the content. Llama generates summaries, keyword clusters, sentiment and spam classification.
- Publish clean data. Normalized JSON feeds the website, search index and downstream publishing systems.
The result
The platform helped turn roughly seven static pages into more than 150,000 pages indexed by Google. Traffic increased by over 600,000 percent, with daily visitors regularly exceeding 50,000. The important result was not transcription. It was a system that turned an existing content asset into sustained audience growth.