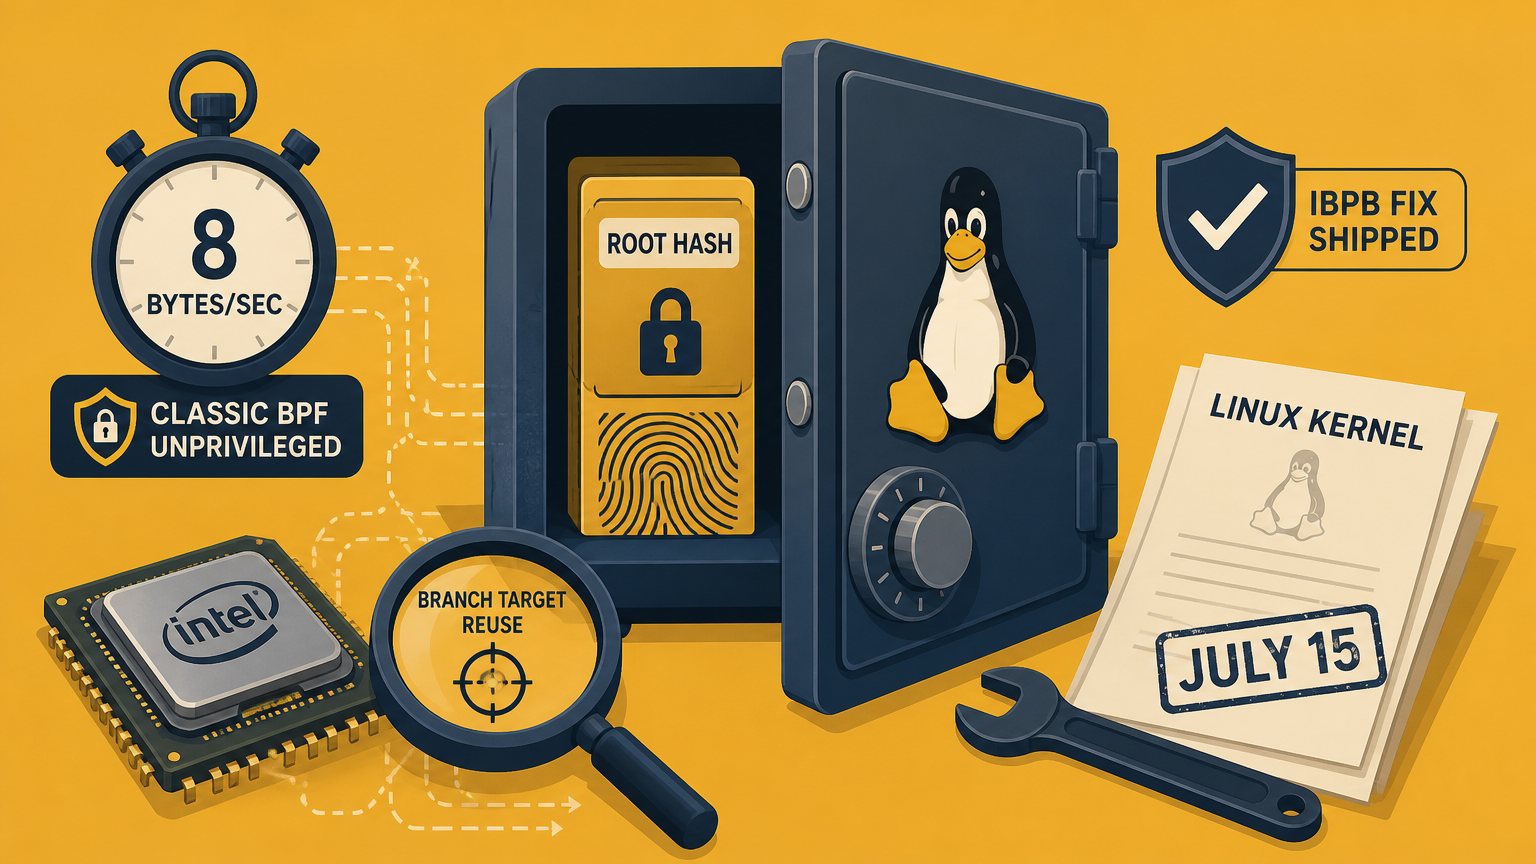
A new Spectre v2 attack called Branch Target Reuse leaks Linux kernel memory at 8 bytes per second from an unprivileged process, and it does it on hardware that has every current Spectre mitigation turned on. Researchers at VUSec at VU Amsterdam and Scuola Superiore Sant'Anna in Italy published the work on September 29. In their demo, the exploit pulls the root password hash out of /etc/shadow in about three minutes on an Intel Raptor Cove core and about five on Lion Cove. The paper is accepted at ACM CCS 2026.
The kernel fix has been in stable trees since July. The mitigation is an IBPB flush. If you run Linux boxes and you haven't rebooted onto a kernel from the last two months, that is the item for today.
Stale predictions outlive the code
Every Spectre v2 attack is about the branch target buffer, the CPU structure that guesses where an indirect jump will land. BTR finds a new way to poison it, and the trick is memory reuse inside one process rather than training from another one.
A JIT engine allocates a chunk of executable memory, writes code into it, runs it, frees it, and later writes different code to the same address. The CPU keeps the architectural view coherent when code is modified. It does not flush the branch predictor entries that pointed into the old code. So an attacker trains an indirect branch in a chunk they control, frees the chunk, and gets a new chunk allocated at the same address. The stale prediction now points into the middle of new code, at an address the attacker picked. The CPU speculatively runs whatever bytes sit there, including instructions that only exist when you decode the stream at a misaligned offset. VUSec calls the primitive a speculative execute-after-free.
That misaligned decode is what makes this bite in the kernel. Linux ships a hardening option, net.core.bpf_jit_harden, that "blinds" constants in JIT output so an attacker can't smuggle instruction bytes through immediates. The researchers encoded their gadget bytes in jump offset fields instead. The aligned view is a valid chain of jumps. The misaligned view is the gadget. Constant blinding did not stop the exploit, and the leak still finished inside five minutes with blinding on.
Three engines were tested. Classic BPF in the Linux kernel, which any user can reach by attaching a socket filter with no capability at all. SpiderMonkey, the JavaScript and WebAssembly engine in Firefox, where the estimated leak rate is tens of bytes per second. And Oracle's GraalVM, running Python through GraalPy, where the exploit was blocked in practice because the engine's own compilation and garbage collection kept wiping the predictor state before the attack could land. The team says that limitation "does not appear fundamental."
Intel, AMD and Arm parts were all affected in testing. There is no microcode fix coming, because the vendors don't consider this a hardware defect. The barrier instruction exists. Software has to issue it.
The fix landed in July and you may already have it
Two CVEs cover the kernel side. CVE-2026-64507 is "x86/bugs: Enable IBPB flush on BPF JIT allocation." CVE-2026-64508 is "bpf: Support for hardening against JIT spraying." Pawan Gupta at Intel wrote the six-patch series, and it went into stable kernels starting July 15, 2026. It merged upstream in 7.2-rc2 and was backported to 6.1, 6.6, 6.12, 6.18 and 7.1. OSV lists the affected range as everything from 5.18.0 up to the first fixed release in each series. On Debian, bookworm got it in 6.1.187-1 and trixie in 6.12.100-1.
The approach is blunt. When the BPF JIT allocator hands out memory that was used before, the kernel issues an IBPB, which flushes indirect branch predictions on the core. Two details keep the cost down:
- The flush only fires for classic BPF, the unprivileged path. eBPF loading already requires CAP_BPF or root, so those allocations skip it.
- The pack allocator tracks which memory packs are "dirty" and prefers ones that won't need a flush, and it skips the IBPB if the BPF dispatcher is already going through a retpoline.
IBPB is not free. Every flush throws away prediction state the core spent time building. But cBPF program loads are rare events on a server compared to, say, syscalls, so in practice the tax is on the process that attaches a socket filter, not on the machine. That is the right trade. If the flush had to run on every context switch, this would be a different conversation about a different percentage.
The knobs you might reach for don't help here. kernel.unprivileged_bpf_disabled=1 blocks unprivileged eBPF and leaves classic socket filters alone, so it doesn't close the door the exploit walks through. bpf_jit_harden=2 is the constant blinding that the paper bypasses. The only fix is the kernel with the flush in it.
Containers sit right on top of this
Seccomp filters are classic BPF. Every Docker default profile, every Kubernetes pod with a seccomp policy, every Chrome renderer sandbox, and every systemd unit with a SystemCallFilter line loads a cBPF program into the kernel. SecurityWeek's writeup lists Docker and Chrome as affected through exactly this path.
That cuts two ways. The sandbox itself is the attack surface: a process inside a container can attach its own socket filters and run the exploit against the host kernel, and a root hash in a container host's memory is a real prize. And the mitigation has to touch the seccomp load path, which is on the hot path for container start. The pack allocator work in patches four through six exists so that starting a thousand pods doesn't mean a thousand predictor flushes. I would still measure it on any node that starts and stops containers by the second, because "rare" is a claim about workloads, and yours may not match the kernel developers' assumptions.
I keep coming back to the fact that this hardening shipped in a July stable batch with a boring subject line, and most people running current LTS kernels have had it for weeks without knowing why. That is the kernel security process working. It is also a reminder that the CVE feed for Linux is now so noisy that "hardening against JIT spraying" reads like a routine cleanup rather than "unprivileged root hash leak on every x86 box."
Hardware guards don't close this either
Intel's IBT and Arm's BTI are supposed to make misaligned landing sites unreachable, because an indirect branch can only land on an endbr64 marker. The paper shows two gaps. On older Intel cores, several instructions can execute speculatively before the IBT check catches the missing marker, so the gadget already ran. VUSec says Lion Cove is the first Intel generation where that race is closed. And where constant blinding is off, an attacker can inject the endbr64 byte pattern itself through misaligned execution, manufacturing a valid landing site. Race-free IBT plus constant blinding together is the combination they rate as a much stronger defense. Neither alone.
The browser side is slower. Mozilla told the researchers it is prioritizing finishing site isolation in Firefox rather than adding IBPB flushes to SpiderMonkey's code cache. That is a reasonable call for a browser, where the flush cost would land on pages that lean on the JIT, and site isolation limits what's in the process to leak. It also means that until that work is complete, a page can in principle read tens of bytes per second out of its own renderer process. Oracle went the other way and now randomizes where GraalVM places its JIT code cache, which breaks the "same address" step of the attack.
My read for people running systems: patch level is the whole story. BleepingComputer reports the fixes are merged and the researcher advice is to update the kernel, and there is nothing else to do on the server side. Check the running kernel against your distro's fixed version and reboot the ones that are behind. Any box where untrusted users share a kernel goes first. Firefox users are waiting on site isolation. And the 8 bytes per second number will go up. The GraalVM result is the only one where the attack failed, and the authors already said why they expect that to change.