Mojo 1.0 shipped on August 12, 2026, with a stability commitment aimed at teams considering it for production. The release also brings simpler language features, better editor support, and compiler checks for some memory-safety errors. Its standard library is available under Apache 2.0, although the compiler remains closed source.
For AI infrastructure teams, the main attraction is hardware portability. Performance-critical kernels written for Nvidia's CUDA stack are difficult to move to another vendor's hardware. Mojo offers a way to write those kernels against a compiler framework designed to support different targets. Published research shows competitive results on some workloads, but it doesn't establish Mojo as a general replacement for CUDA.
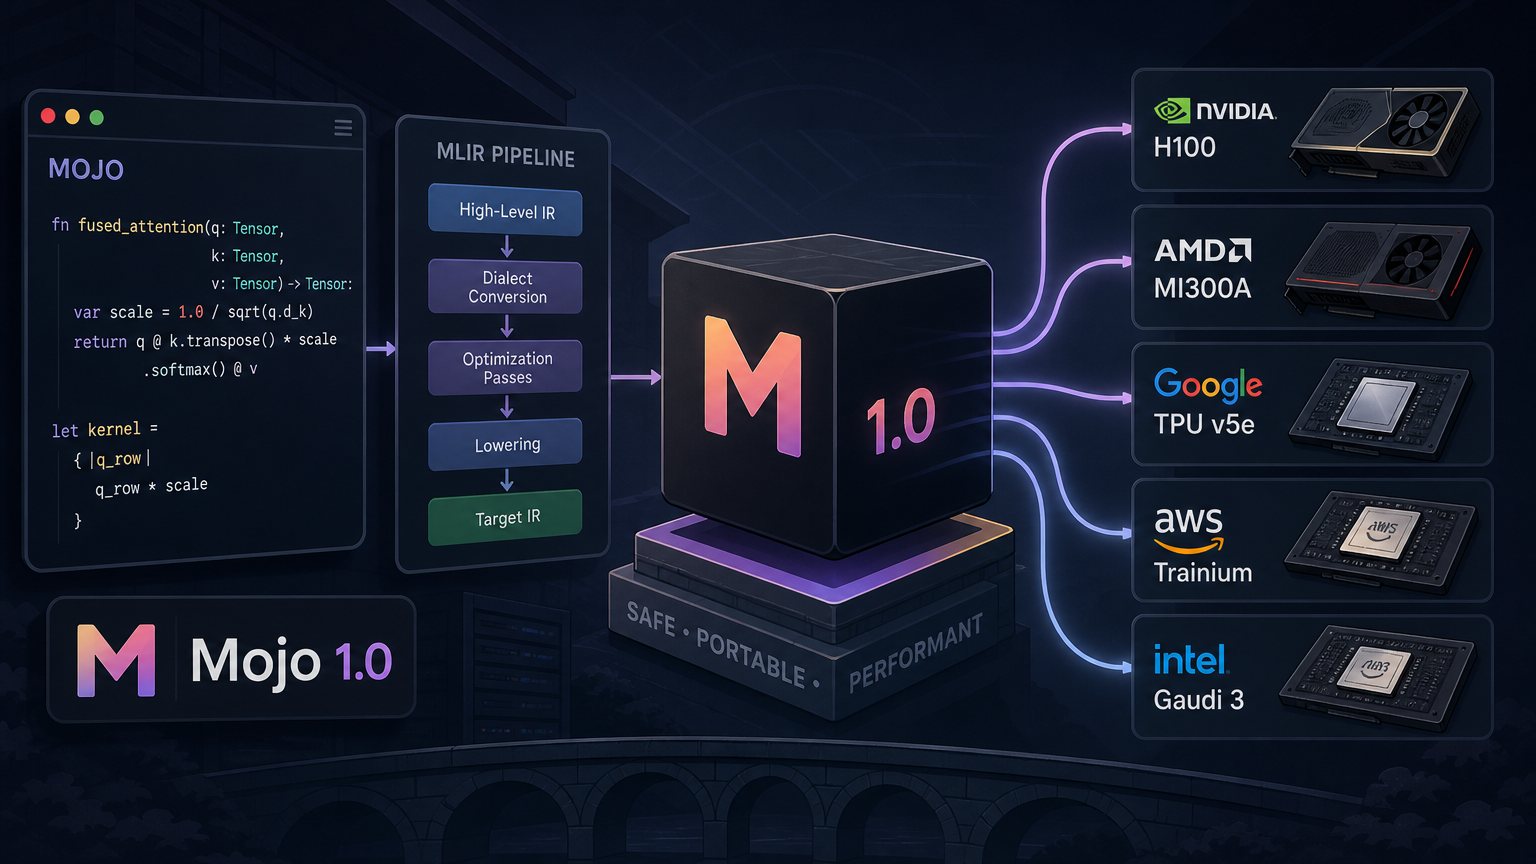
Mojo was created by Chris Lattner, whose previous work includes LLVM, Clang, and Swift. It uses MLIR, or Multi-Level Intermediate Representation, a compiler framework also used for Google's TPUs and a growing number of custom AI chips. That foundation explains both Mojo's promise and the engineering still needed to deliver it.
How Mojo targets different hardware
MLIR lets a compiler represent a program at several levels of detail before generating machine code. A series of transformations, called lowering passes, converts higher-level operations into forms suited to a particular processor.
An Nvidia H100 and an AMD MI300A can therefore use different lowering paths from the same source code. In principle, support for a custom ASIC with an unusual memory hierarchy could be added through new compiler passes, allowing existing Mojo kernels to run on it. That depends on the backend support being implemented and working well. A shared source language alone doesn't guarantee equal performance across chips.
Mojo's portability argument centers on this compiler infrastructure, rather than treating CUDA as the interface that everything else must accommodate. Triton, TVM, and AMD's ROCm also address parts of the portability problem, though they shouldn't be assumed to use interchangeable approaches.
A 2025 study from Oak Ridge National Laboratory and the University of Tennessee tested Mojo kernels against CUDA and HIP baselines across four scientific workloads on H100 and MI300A hardware. The reported results showed Mojo matching CUDA on memory-bound kernels and sometimes exceeding it in BabelStream operations. The explanation given for those gains was that MLIR optimization passes reduced register memory operations compared with CUDA's toolchain.
Memory-bound work spends much of its time moving data rather than doing arithmetic. Competitive results there are relevant to inference infrastructure, where memory movement can be a major constraint. The SC '25 paper provides third-party evidence for a specific claim: Mojo can achieve near-native performance on tested memory-bound workloads across H100 and MI300A hardware.
The gaps matter too. Compute-bound kernels that depend on atomic operations showed measurable performance deficits on AMD hardware. Atomic operations coordinate updates to shared data, so that limitation could matter for work such as gradient accumulation in distributed training. The results justify testing representative inference kernels; they don't justify assuming every training or inference workload will perform equally well.
What the 1.0 commitment covers
A 1.0 release matters when it gives developers a clearer basis for maintaining code. Modular's stated commitment is to make primarily additive changes during the 1.x lifecycle and handle breaking changes using patterns associated with mature languages such as C++. That is a stability policy, not a promise that nothing will ever change.
The release announcement also identifies the standard library as Apache 2.0 licensed. That gives teams access to the library's source under a permissive license, but it doesn't extend to the still-closed compiler.
Several language and tooling changes have practical consequences:
- Unified closure syntax. Python-style lambda syntax supports inline closures. This is useful when GPU kernel code needs to pass computations as values without heap-allocating closures.
- Consistent variable declarations. Variables are consistently declared with
var, removing ambiguity in earlier versions that could lead to subtle bugs in complex kernel code. - A single Pointer type. The release consolidates four earlier pointer types with overlapping semantics. A simpler pointer model matters in code that manages memory manually, particularly performance-critical paths.
- Improved language server support. The Language Server Protocol integration used by VS Code and other editors is described as substantially more stable. Reliable editor tooling reduces the friction of working in a young language.
- Reference invalidation diagnostics. The compiler catches patterns such as appending to a
Listwhile a live reference points into it. An append can invalidate that reference, making this a useful category of error to catch before execution.
Mojo's memory model draws from Rust, with compile-time ownership tracking, no garbage collector, and an explicit transfer operator, ^, for moving ownership of non-copyable types. Developers familiar with Rust's borrow checker should recognize much of the model. Others will need to learn how ownership and references constrain their code.
That learning cost comes with an operational benefit. Performance-critical code can avoid garbage-collection pauses, while compiler diagnostics catch some memory errors before deployment. Those properties are useful for latency-sensitive systems, though they don't remove the need to test memory handling and performance.
Where CUDA dependence becomes expensive
When Nvidia launched CUDA in 2007, it gave developers a practical way to write general-purpose GPU code without working around graphics interfaces such as OpenGL. Its tooling and ecosystem remain a major reason custom AI kernels are written for Nvidia hardware.
The hardware choices now extend well beyond one vendor. An AI operator may need to accommodate Nvidia A100s and H100s, AMD MI300As, Google TPUs through GCP, AWS Trainium and Inferentia, or Intel Gaudi. CUDA code doesn't directly cover all those targets.
PyTorch abstractions help at the application level. Custom attention variants, fused operations, and quantization kernels still often require lower-level work, where CUDA's tooling makes it the default choice. Moving those kernels to another platform can mean additional implementations, tuning, and maintenance.
Mojo's proposal is to keep more of that work in one language and let target-specific compiler passes handle the differences. The Oak Ridge and University of Tennessee results support that proposal for a limited set of scientific workloads. They don't establish that every listed accelerator has a production-ready Mojo backend or that an existing CUDA kernel can be moved without changes.
The compiler is still a dependency risk
As of the morning of August 12, 2026, Modular had committed to open-sourcing the Mojo compiler and toolchain during 2026, but had not yet done so. The open standard library is useful; the compiler is the component needed to keep building and extending the language independently.
Lattner's announcement on the Modular forum hints that a compiler source release may come at Modular's conference the following week. If that happens, outside contributors could begin working on compiler backends directly. LLVM provides a precedent for a compiler project developing through broad participation, though Mojo's future contribution rate remains uncertain.
The reported community figures already include nearly 200 contributors, more than 1,100 pull requests, and over 200,000 lines of code contributed to the existing release artifacts. Opening the compiler could expand the work available to that community.
Until then, operators need to account for their dependence on Modular. It is a venture-backed company that could change direction, be acquired, or shut down. If compiler development stopped while the source remained closed, users could be left maintaining Mojo systems with the last available toolchain and no straightforward way to extend it. Apache 2.0 licensing for the standard library doesn't resolve that risk.
Which teams should evaluate it
Most application teams have little reason to migrate immediately. There is no automatic migration path from Python or Rust, the third-party library ecosystem is young, and the performance gaps around compute-bound atomic operations may affect some production workloads.
Infrastructure teams writing custom inference kernels have a stronger reason to evaluate Mojo. Attention kernels and quantization logic are useful candidates, especially where maintaining CUDA-only code already complicates hardware choices. The evaluation needs to use the team's own workload and intended hardware rather than treating the published memory-bound results as a general performance guarantee. An open-source compiler release would also reduce an important adoption risk.
For teams using Modular's MAX inference framework, the release has more immediate relevance because MAX uses Mojo internally. A primarily additive 1.x policy offers a more predictable foundation for development and maintenance, within the limits of Modular's stated compatibility commitment.
Mojo has credible compiler engineering behind it and early third-party performance evidence worth investigating. Adoption depends on whether the required backend works, whether representative kernels perform well, and whether the toolchain's licensing and maintenance risks are acceptable.